Nine-year-old Nvidia Tesla V100s fight again: a 4-GPU cluster beats two DGX Sparks at AI inference9 年前英伟达 Tesla V100 老将再战:4 GPU 集群 AI 推理跑赢 2 台 DGX Spark
YouTube channel Jun Yamog tested four Tesla V100s on an NVLink carrier board; on the Qwen3.8-Flash-Next benchmark, long-prompt processing was 230% faster than an M5 Ultra and 40% faster than two DGX Sparks…
IT之家 10 月 13 日消息,YouTube 频道 Jun Yamog 昨日(10 月 12 日)发布视频,测试将 4 张 Tesla V100 安装于 NVLink 载板,在 Qwen3.8-F…
Key Points要点速览
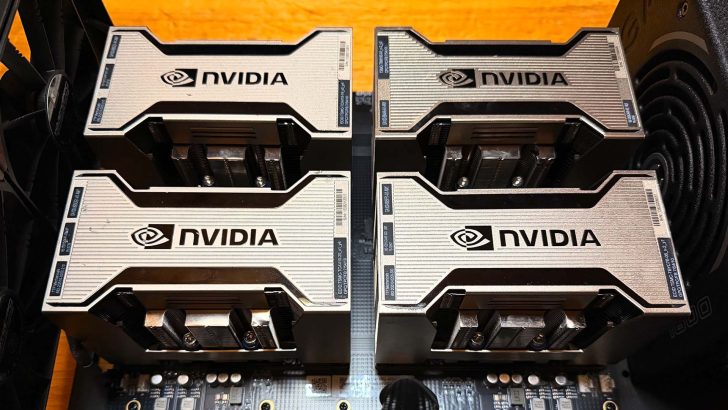
YouTube channel Jun Yamog published a video on 12 October testing four Tesla V100s mounted on an NVLink carrier board; on the Qwen3.8-Flash-Next benchmark, long-prompt processing was 230% faster than an M5 Ultra and 40% faster than two DGX Sparks. Tesla V100 is Nvidia’s 2017 data-centre GPU based on the Volta architecture, widely used for AI training and inference; the 32GB version has HBM2 memory at 900GB/s. NVLink is Nvidia’s high-speed GPU interconnect for moving data directly between GPUs, cutting the interconnect bottleneck compared with PCIe in multi-GPU servers and AI clusters. The carrier board offers 300GB/s of bandwidth and six NVLink 2.0 connections. To house four separate GPUs the tester modified an Nvidia A100 heatsink to dissipate roughly 300W per V100 and connected the board over PCIe x8. The host ran a 4-bit quantised Qwen3.8-Flash-Next and compared it with two DGX Sparks with 128GB of unified LPDDR5X memory and a Mac Studio with an M5 Ultra. In long-prompt processing the four V100s were 40% faster than the DGX Spark pair and 230% faster than the M5 Ultra; the tester notes the huge gap with Apple Silicon may partly reflect insufficient software optimisation. In short-prompt processing the V100 cluster kept a 40% lead over the DGX Sparks and was 163% faster than the M5 Ultra, showing older data-centre GPUs still deliver high throughput on certain inference workloads. In short-prompt token generation the four V100s hit 100.6 tok/s, 121% faster than two DGX Sparks; the M5 Ultra managed 44.5 tok/s.
IT之家 10 月 13 日消息,YouTube 频道 Jun Yamog 昨日(10 月 12 日)发布视频,测试将 4 张 Tesla V100 安装于 NVLink 载板,在 Qwen3.8-Flash-Next 基准中, 长提示处理速度较 M5 Ultra 快 230%,较 2 台 DGX Spark 快 40%。 IT之家查询公开资料,Tesla V100 是英伟达于 2017 年推出的数据中心 GPU,基于 Volta 架构,常用于 AI 训练与推理。其 32GB 版本配备 HBM2 显存,900GB/s 显存带宽可支持大模型参数与数据的快速读取。 NVLink 是英伟达的 GPU 高速互联技术,用于在多颗 GPU 之间直接传输数据。相比通过 PCIe 通信,NVLink 可降低互联瓶颈,常用于多 GPU 服务器和 AI 计算集群。 该 NVLink 载板提供 300GB/s 带宽,并配备 6 条 NVLink 2.0 连接。为容纳 4 颗独立 GPU,测试者改装 NVIDIA A100 散热器,让其可散发每颗 V100 约 300W 的功耗,并通过 PCIe x8 接口连接载板。 该主播使用 4-bit 量化的 Qwen3.8-Flash-Next 模型测试,对比对象包括 2 台配备 128GB LPDDR5X 统一内存的 DGX Spark,以及配备 M5 Ultra 芯片的 Mac Studio 设备。 在长提示处理测试中,4 颗 V100 较 DGX Spark 集群快 40%,较 M5 Ultra 快 230%。测试者指出,与 Apple Silicon 的巨大差距可能部分源于软件优化不足。 在短提示处理测试中,V100 集群较 DGX Spark 保持 40% 的速度优势,较 M5 Ultra 快 163%。该结果显示,旧款数据中心 GPU 在特定推理负载中仍具备较高吞吐能力。 在短提示 Token 生成测试中,4 颗 V100 达到 100.6 tok/s,较 2 台 DGX Spark 快 121%;M5 Ultra 的成绩为 44.5 tok/s。
想马上用起来?去「AI工具」栏挑一个直接下载,或在「AI教程」里跟着图文步骤做一遍。
去 AI工具 → 看 AI教程 →阅读与点赞数据保存在你的浏览器本地,欢迎留下你的想法。
 今日正能量学一点,用一点;今天种下的种子,会长成明天的能力。去免费下载专区 →广告
评论 文明发言,让讨论更有价值