OpenAI Releases Latest Chip Design Results: AMD's Flagship GPU PPA Improves by Up to 14%, and the Size of Its Self-Developed Chip Jalapeño Is Reduced by Up to 13%OpenAI 发布芯片设计最新成果:AMD 旗舰 GPU PPA 最高提升 14%,自研芯片 Jalapeño 面积最高减少 13%
According to a report from IT Home on 19 November, OpenAI released its latest technical report, "Advancing chip design with OpenAI models", on 18 November (local time), disclosing the use of AI models…
IT之家 11 月 19 日消息,OpenAI 于当地时间 11 月 18 日发布最新技术报告《Advancing chip design with OpenAI models》,披露了利用 AI 模…
Key Points要点速览
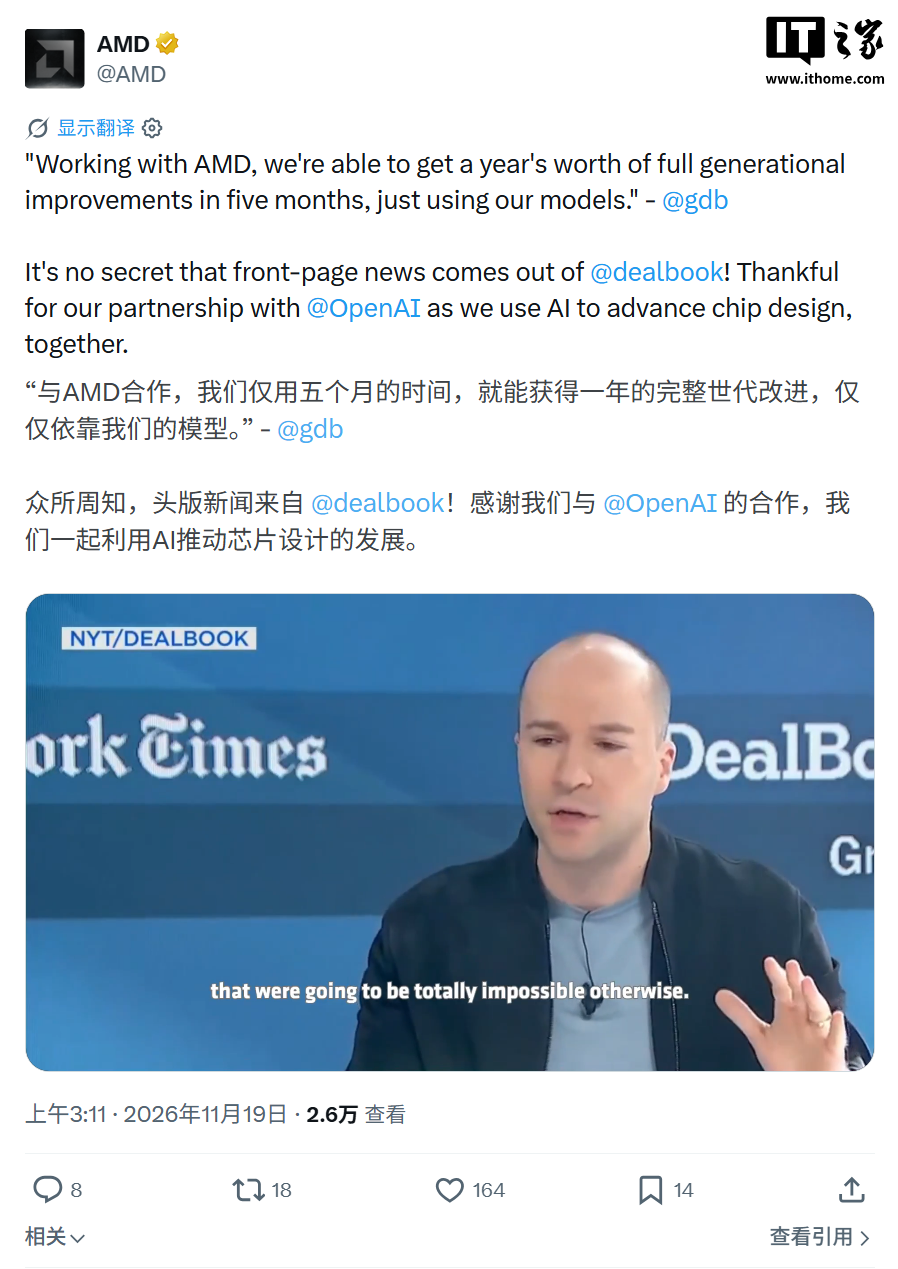
According to IT Home on 19 November, OpenAI released its latest technical report, "Advancing chip design with OpenAI models", on 18 November (local time), revealing the latest progress in using AI models to assist in chip design. According to the report, OpenAI has applied the relevant technology to its self-developed inference chip, Jalapeño, as well as to the design optimisation of AMD's next-generation GPUs and CPUs. It has also used open-source RISC-V processor tests to evaluate the chip design capabilities of different generational models. OpenAI stated that as early as the beginning of 2025, engineers began using GPT-4o to assist in the design of Jalapeño. Even the model at that time was already able to propose substantial improvements in terms of chip performance, power consumption, and area (PPA). In Jalapeño's vector computation unit, the AI model reduces hardware resource consumption by optimising floating-point adders, multipliers, conversion functions, reduction logic, and special function units. In the matrix computation unit, the AI model successfully improved floating-point operations and low-precision dot product circuits. Among them, one multiplier redesign reduced the area of the synthesised standard cell by approximately 15% while shortening the operation latency from two clock cycles to one clock cycle; another adder design also reduced the area of the standard cell by approximately 15% while maintaining a latency of two clock cycles. OpenAI estimates that the modifications proposed by the model reduce the standard cell area of the Jalapeño vector computation unit by about 13% and the matrix computation unit by about 10%. These optimisations have been validated on real chips. In its collaboration with AMD, the OpenAI model was also involved in optimising the design of GPU and CPU chips. OpenAI claims that on AMD's flagship GPU IP, the model delivered up to a 14% improvement in PPA compared to a highly optimised baseline design. The relevant models further optimised the circuit structure by rewriting the SystemVerilog RTL code that describes the chip's circuitry. OpenAI stated that this is equivalent to compressing about a year's worth of design optimisation progress into less than 5 months. AMD has incorporated some of the optimisation results into chip designs that have recently been sent for manufacturing, while other modifications have been added to production design files for use in future products. In addition, AMD has also validated single-digit percentage PPA improvements delivered by the model in key modules of its next-generation flagship CPU. To evaluate the ability of different generations of AI models to independently complete chip design tasks, OpenAI also selected two open-source 32-bit RISC-V processor cores for testing: PicoRV32, which is designed for FPGAs, and Ibex, which serves as the embedded processor for the OpenTitan security chip. During the test, OpenAI provided the model with the original hardware description code, asking it to increase the processor's throughput and verify the correctness of the design through simulation. For designs that pass the verification, the researchers also calculate the number of instructions executed per second by combining the number of instructions per clock cycle under the hidden test load with the maximum clock frequency estimated by Yosys. If the design fails the correctness check, or if the chip area exceeds 16 times that of the original design, it is scored as zero. The test results show that, with a budget of approximately 112,000 tokens per run, GPT-6. 2 Astra achieved the highest average scores on both the PicoRV32 and Ibex processors. When optimising based on the existing PicoRV32 core, GPT-6.2 Astra scored approximately twice as high as GPT-6 Astra under a similar budget. OpenAI also conducted another test: instead of asking the model to optimise an existing processor, it provided written specifications and code templates directly, allowing the model to design a RISC-V processor core from scratch and decide for itself how data would flow and how the pipeline stages would be divided. In this task, all five models involved in the test scored higher than when optimising existing designs, with a computational budget of approximately 112,000 tokens. IT Home noted that the entire evaluation covered two design tasks, two processor cores, and different token budgets, comprising a total of 9,881 scored runs. However, OpenAI also pointed out that when redesigning the processor from the specifications, the model may omit features such as performance counters and additional instructions from the original chip, and these features have limited help for the throughput targets in the tests, which may partly explain the improvement in scores. If the model is required to retain these features, further limit the circuit area, and check the timing after physical synthesis, the test results will be closer to actual mass-production chip design scenarios. Regarding future plans, OpenAI has announced a partnership with electronic design automation (EDA) software vendor Synopsys to train a new model called GPT-Synopsys, enabling it to use Synopsys' EDA tools like a professional chip designer to complete chip design and verification tasks. OpenAI stated that this study demonstrates that AI models are not only capable of exploring new processor architectures but are also able to propose further optimisation solutions based on complex mass-production designs such as Jalapeño and AMD's next-generation flagship GPUs and CPUs.
IT之家 11 月 19 日消息,OpenAI 于当地时间 11 月 18 日发布最新技术报告《Advancing chip design with OpenAI models》,披露了利用 AI 模型辅助芯片设计的最新进展。 据介绍,OpenAI 已将相关技术应用于自研推理芯片 Jalapeño,以及 AMD 下一代 GPU 和 CPU 的设计优化,并通过开源 RISC-V 处理器测试评估不同代际模型的芯片设计能力。 OpenAI 表示,早在 2025 年初,工程师就开始使用 GPT-4o 辅助设计 Jalapeño。即使是当时的模型,也已经能够在芯片性能、功耗和面积(PPA)方面提出实质性改进方案。 在 Jalapeño 的向量计算单元中,AI 模型通过优化浮点加法器、乘法器、转换函数、归约逻辑和特殊功能单元,减少硬件资源占用。 在矩阵计算单元中,AI 模型成功改进了浮点运算和低精度点积电路。其中,一项乘法器重新设计方案使综合后的标准单元面积减少约 15%,同时将运算延迟从两个时钟周期缩短至一个时钟周期;另一项加法器设计也将标准单元面积减少约 15%,同时保持两个时钟周期的延迟。 OpenAI 估算,模型提出的修改使 Jalapeño 向量计算单元的标准单元面积减少约 13%,矩阵计算单元减少约 10%。这些优化已经通过实际芯片验证。 在与 AMD 的合作中,OpenAI 模型也参与了 GPU 和 CPU 芯片设计优化。OpenAI 称,在 AMD 旗舰 GPU IP 上,相较于经过高度优化的基准设计,模型带来了最高 14% 的 PPA 改进。相关模型通过重写描述芯片电路的 SystemVerilog RTL 代码,进一步优化了电路结构。OpenAI 表示,这相当于将约一年的设计优化进展压缩到不到 5 个月内完成。 AMD 已经将部分优化成果纳入近期送交制造的芯片设计,其他修改则被加入生产设计文件,供后续产品使用。此外,AMD 还在其下一代旗舰 CPU 的关键模块中验证了模型带来的个位数百分比 PPA 提升。 为评估不同代际 AI 模型独立完成芯片设计任务的能力,OpenAI 还选择了两款开源 32 位 RISC-V 处理器内核进行测试,分别是面向 FPGA 的 PicoRV32,以及作为 OpenTitan 安全芯片嵌入式处理器的 Ibex。 测试中,OpenAI 向模型提供原始硬件描述代码,要求其提高处理器吞吐量,并通过仿真检查设计正确性。对于通过检查的设计,研究人员还会结合隐藏测试负载下的每时钟周期指令数和 Yosys 估算的最高时钟频率,计算每秒执行指令数。若设计未通过正确性检查,或者芯片面积超过原始设计的 16 倍,则记为零分。 测试结果显示,在每次运行预算约为 11.2 万 Token 的条件下,GPT-6.2 Astra 在 PicoRV32 和 Ibex 两款处理器上的平均得分均最高。以现有 PicoRV32 内核为基础进行优化时,GPT-6.2 Astra 在相近预算下的得分约为 GPT-6 Astra 的两倍。 OpenAI 还进行了另一项测试:不再要求模型优化现有处理器,而是直接提供书面规格和代码模板,让模型从零设计 RISC-V 处理器内核,自行决定数据流动方式和流水线阶段划分。 在这一任务中,所有五款参与测试的模型,在约 11.2 万 Token 的运行预算下,得分均高于优化现有设计时的表现。IT之家注意到,整个评估覆盖两种设计任务、两款处理器内核及不同 Token 预算,共包含 9881 次计分运行。 不过,OpenAI 也指出,从规格重新设计处理器时,模型可能省略原有芯片中的性能计数器和额外指令等功能,而这些功能对测试中的吞吐量目标帮助有限,因此可能部分解释得分提升。若要求模型保留这些功能、进一步限制电路面积,并在物理综合后检查时序,测试结果会更接近实际量产芯片设计场景。 在后续计划方面,OpenAI 宣布与电子设计自动化(EDA)软件厂商新思科技(Synopsys)合作,训练名为 GPT-Synopsys 的新模型,使其能够像专业芯片设计人员一样使用新思科技的 EDA 工具,完成芯片设计与验证工作。 OpenAI 表示,此次研究证明,AI 模型不仅能够探索新的处理器架构,也已经能够在 Jalapeño 以及 AMD 下一代旗舰 GPU、CPU 等复杂量产设计基础上提出进一步优化方案。
想马上用起来?去「AI工具」栏挑一个直接下载,或在「AI教程」里跟着图文步骤做一遍。
去 AI工具 → 看 AI教程 →阅读与点赞数据保存在你的浏览器本地,欢迎留下你的想法。
 今日正能量学一点,用一点;今天种下的种子,会长成明天的能力。去免费下载专区 →广告
评论 文明发言,让讨论更有价值